Monitoring
Alerts
Get told when capture breaks, verification fails, rotation stops or backups go stale. Webhook events and Prometheus metrics.
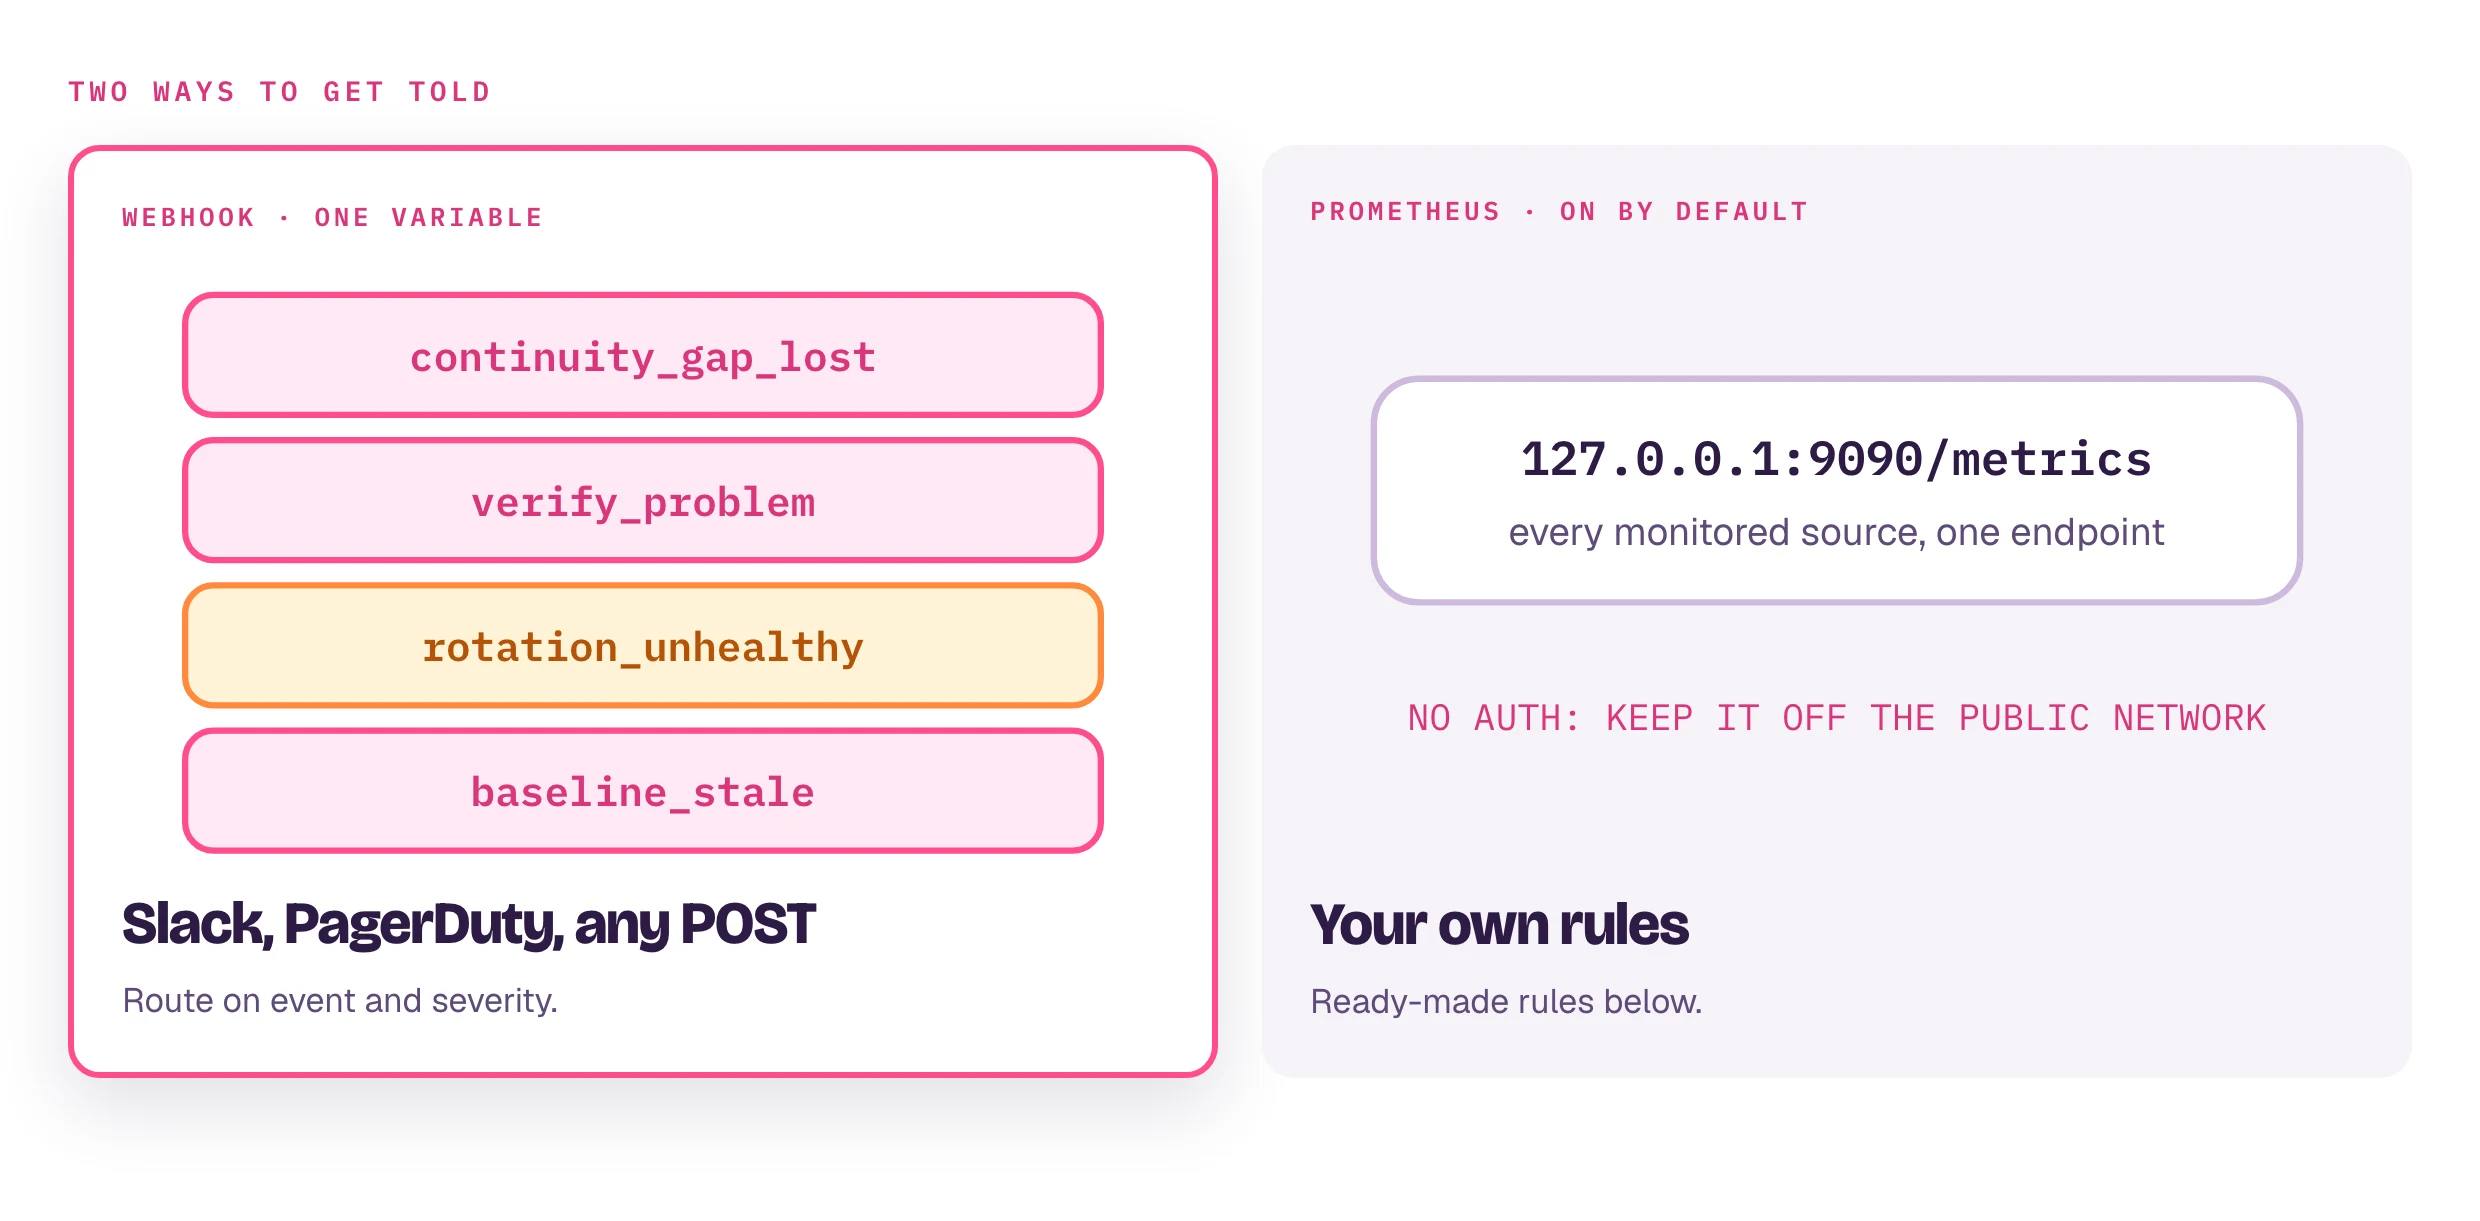
Webhook
# docker-compose.yml, console service environment
BINTRAIL_CONSOLE_NOTIFY_WEBHOOK: https://hooks.example.com/dbtrail
CLI: bintrail-console watch --notify-webhook <url>. A URL that is not http
or https stops the daemon at startup.
event | Severity | Sent when |
|---|---|---|
continuity_gap_lost | critical | Capture lost events for good |
verify_problem | warning or critical | A verification run found a mismatch or failed |
rotation_unhealthy | warning | Rotation made no progress; the index keeps growing |
baseline_stale | critical | The newest backup is older than the change history; full-table restore through the gap is impossible |
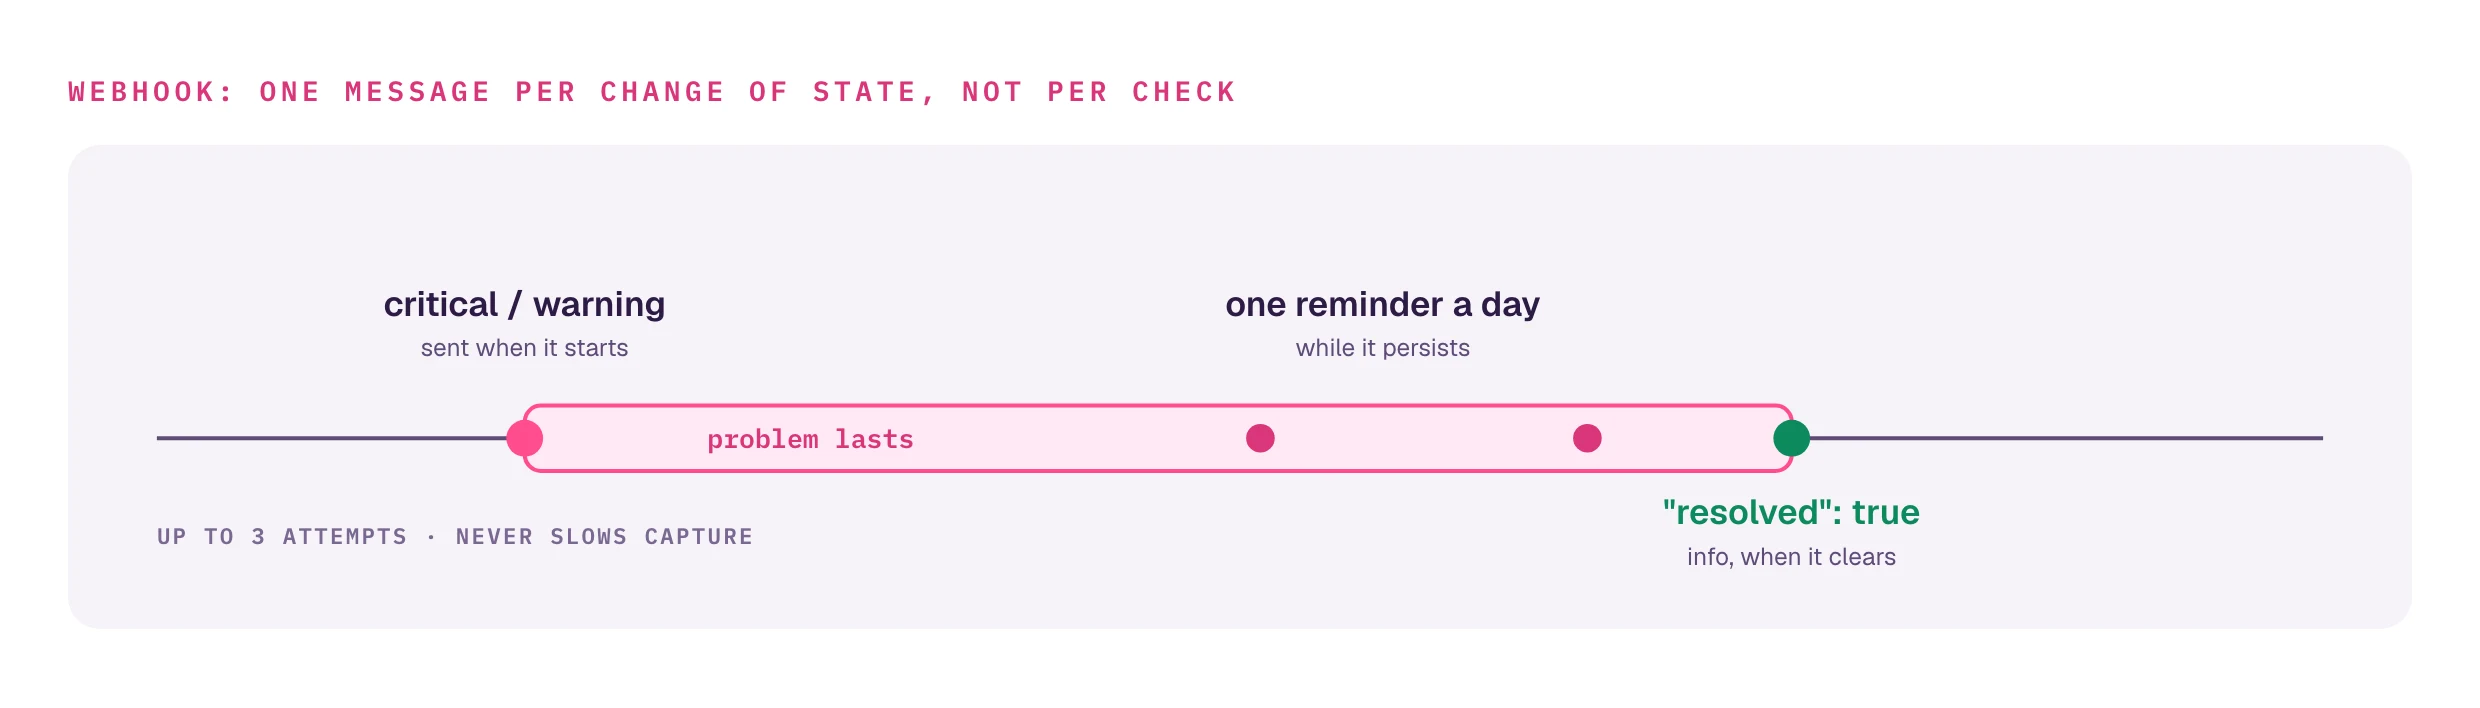
{
  "event": "continuity_gap_lost",
  "severity": "critical",
  "server": "shop-primary",
  "summary": "capture continuity lost: events in the gap are PERMANENTLY unrecoverable; re-baseline to resume trustworthy coverage",
  "timestamp": "2026-09-14T10:02:11Z"
}
Prometheus
- Bundled stack:
127.0.0.1:9090/metrics; a Prometheus container on the same Compose network scrapesbintrail:9090. Off:METRICS_ADDR=in.env. - No authentication. Widen past loopback only behind a firewall.
- Headless:
--metrics-addr :9090onbintrail streamorbintrail-console watch.
# Capture stopped making data recoverable (dead daemon OR broken stream)
time() - bintrail_stream_last_flush_timestamp_seconds > 300

# Events permanently lost
bintrail_continuity_gap_lost == 1

# Hours rotated out with no archive
bintrail_index_gap_hours > 0

# Recovery no longer reaches back 7 days
bintrail_index_retention_horizon_seconds < 7 * 24 * 3600

# Rotation failing or refusing to drop unarchived hours
bintrail_rotation_healthy == 0

# No conclusive verification run in 2 days
time() - bintrail_verify_last_run_timestamp_seconds > 2 * 24 * 3600

# Index disk, 7-day projection
predict_linear(bintrail_index_storage_bytes{location="mysql"}[6h], 7 * 24 * 3600)

# Changes the index will never contain
rate(bintrail_statement_dml_dropped_total[5m]) > 0
rate(bintrail_unhandled_rows_dropped_total[5m]) > 0
Do not alert on a lag gauge alone
Lag gauges move only with traffic. A dead stream freezes them at "caught up".
The flush-timestamp rule catches that; bintrail_stream_replication_lag_seconds > N
does not.
Every metric, label and scrape config: observability reference.
Cron without Prometheus
bintrail status --index-dsn "$IDX" --fail-on-gap || page-someoneNon-zero on a lost gap and when continuity cannot be evaluated.